Understanding memory and data in RFID and NFC tags
The physical size and memory capacity of your tags directly dictate how much information your tracking system can process locally. When you evaluate different hardware options, you will quickly notice that smaller memory capacities often lead to faster read times and lower overall costs for your project. Your team must decide early on whether the tag will simply point to a database record or carry its own detailed payload. Approaching this decision carefully prevents your deployment from becoming bogged down by mismatched hardware capabilities.
Choosing the correct tag capacity ensures that your enterprise software receives data smoothly without experiencing unnecessary bottlenecks. If you over-engineer the solution with massive storage capacities, you might face sluggish performance that frustrates your daily operators. On the other hand, selecting tags with insufficient space forces you to rely entirely on continuous network connectivity to retrieve vital item details. Balancing these factors gives your project managers a clear baseline to build a reliable and cost-effective data architecture.
Typical memory sizes for common tag types
Recognizing the physical capacity range of standard tags helps you realistically gauge what can fit on the hardware versus what belongs in your backend database. You will find that memory sizes vary dramatically based on the intended use case and the specific technology you select. Matching your operational requirements to these typical capacities prevents you from purchasing expensive high-capacity tags when a simpler alternative would suffice. Your integration team can use these benchmarks to design a streamlined and highly responsive architecture.
Low capacity for simple identification
Passive Ultra High Frequency (UHF) tags designed for simple identification typically hold between 96 bits and 512 bits of data. This minimal storage space usually contains an Electronic Product Code (EPC), which acts as a digital license plate for your items. Manufacturers purposely produce these tags to keep production costs low for bulk inventory tracking and retail supply chains. Your system reads this short identifier and instantly links it to comprehensive details stored safely on your central server.
Medium capacity for standard tracking
Standard tracking applications often rely on tags that dedicate 96 to 128 bits specifically to the EPC memory bank. This medium tier provides enough space to hold unique serial numbers that connect directly to your centralized inventory software. Some of these tags also include a small amount of optional user memory, which allows you to store localized data like lot numbers or production dates. Selecting this capacity gives your team a reliable balance between fast transmission speeds and sufficient local identification.
High capacity for offline data logging
High-capacity NFC chips can store between 1 kilobyte (KB) and 8 KB of user memory for more demanding localized applications. While this sounds substantial, 8 KB is still quite limited and only holds short text strings or a small handful of timestamped sensor records. Continuous offline data logging rapidly consumes this space and degrades the standard Electrically Erasable Programmable Read-Only Memory (EEPROM) after a limited number of write cycles. For extensive offline logging, your team should consider active loggers with internal flash memory that use the NFC chip purely as a wireless interface.
How memory is organized within the chip
Storage within these integrated circuits is segmented into different functional areas rather than acting as one single pool of data. Understanding this internal architecture clarifies why certain pieces of information remain permanently locked while other sections can be rewritten continuously. Your technical leads can use this knowledge to discuss data security and system design with the integration team without needing a deep engineering background. This structured approach ensures that you place the right information in the correct secure location on the tag.
Memory banks in standard RFID tags
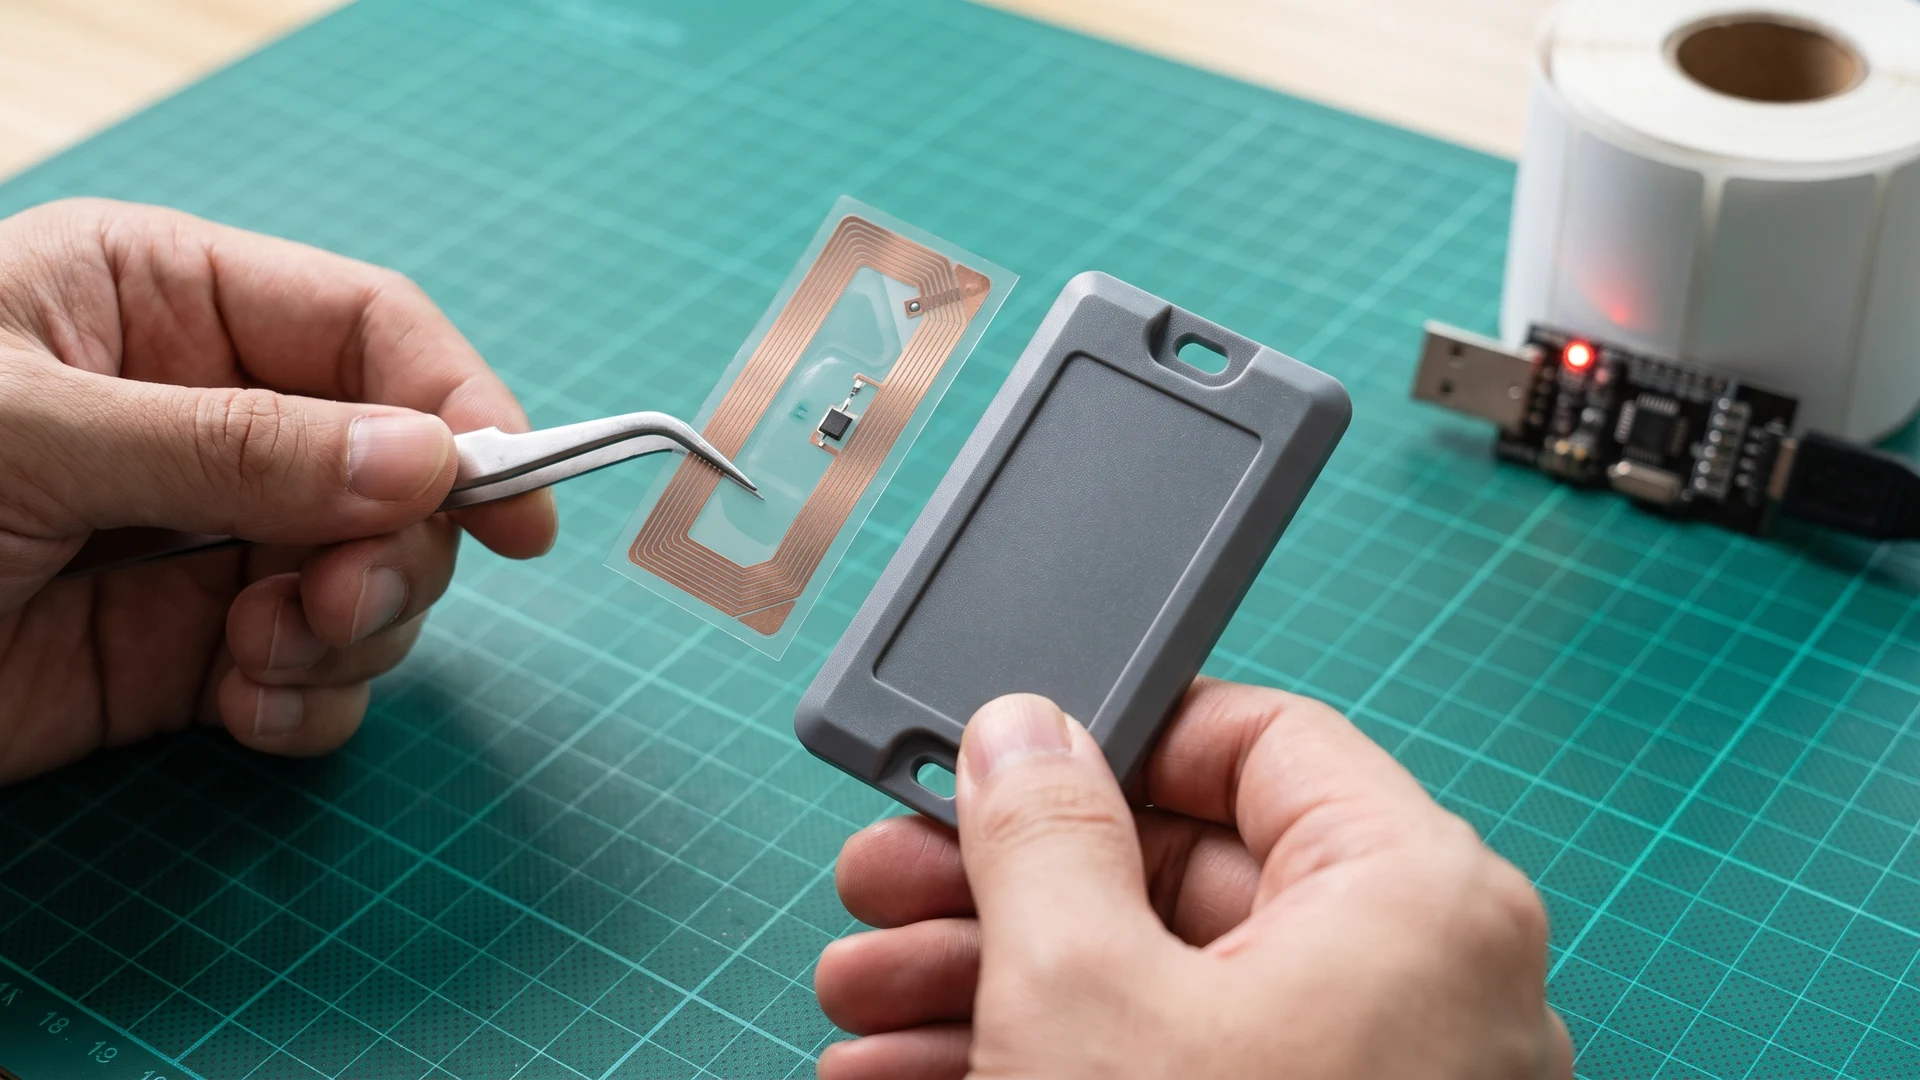
EPC Gen 2 RFID tags organize their internal storage into four distinct logical memory banks that handle different operational tasks. The Reserved memory bank securely holds your access and kill passwords, giving you control over who can read or disable the tag. The Tag Identifier (TID) bank contains a permanent factory-locked serial number that guarantees authenticity and prevents counterfeiting. Finally, the User memory bank provides optional rewritable space for your custom application data, though many basic tags ship with zero bytes in this specific section.
Sector and page structures in NFC chips
NFC chips use a slightly different internal layout that divides the available storage into distinct sectors and smaller pages. Each page typically holds a fixed number of bytes, and your reading devices process the data by accessing these pages sequentially. This specific structural mapping allows the hardware to retrieve information quickly and reliably during the brief moment a user taps the tag. Your software must format its requests to align with these page boundaries to guarantee a smooth and error-free data transfer.
Common data formats used on top of raw storage
Raw bytes on your tags must be formatted into readable structures so that your software systems can process them automatically. For NFC deployments, the industry relies on the NFC Data Exchange Format (NDEF), which organizes binary data into structured messages and records. Each NDEF record includes a header that defines the exact payload type, such as a web link or plain text, alongside the specific payload length. Wrapping raw data in this standardized format ensures that any compatible device can interpret the information without requiring proprietary software.
RFID tags utilize standardized encoding schemes defined by regulatory bodies like EPCglobal to map binary sequences into meaningful business values. These standards partition the available memory into specific bit lengths for headers, company prefixes, and unique item references. Because memory space remains highly constrained, these data fields are packed tightly across byte boundaries rather than aligning to standard character sizes. Standardizing these data formats prevents bottlenecks when connecting your new hardware to existing enterprise software platforms.
Steps to match tag capabilities with your data requirements
Evaluating what data needs to live on the tag versus in the cloud requires a structured sequence of decisions. You must analyze your existing workflows to pinpoint exactly where automated data capture will deliver the most immediate value. Following a concrete action plan helps you finalize your data architecture and confidently select the most appropriate tag hardware. Your team can use these sequential steps to align your physical deployment with your broader software integration goals.
- Audit your existing data infrastructure: Begin by reviewing the centralized databases and enterprise software platforms your organization currently uses daily. You need to determine how quickly these systems can retrieve item details when provided with a simple unique identifier. This initial audit reveals whether you truly need high-capacity tags or if your network can handle the primary data load. Completing this review early prevents you from over-investing in unnecessary local storage.
- Define your offline operational needs: Assess the environments where your tags will be scanned to see if continuous network connectivity is guaranteed. If your workers operate in remote areas without reliable internet, you must store critical item details directly on the tag. Documenting these specific offline requirements guides you toward chips that feature larger rewritable user memory banks. Your operational environment ultimately dictates exactly how much independence your scanning devices require.
- Select the appropriate standardized format: Choose an industry-standard data structure that seamlessly bridges the gap between your physical hardware and your software. If you are deploying consumer-facing tap points, configuring your tags with the NDEF standard ensures universal smartphone compatibility. Selecting the right format early prevents expensive integration delays and eliminates the need to develop custom parsing scripts. This standardization simplifies the entire deployment process for your technical integration team.
- Run a small-scale hardware pilot: Purchase a limited batch of your chosen tags and test them in your actual operational environment. You should verify that the read speeds, memory capacities, and data formats meet the expectations set during your initial planning phase. This practical test run allows you to make vital adjustments before committing a significant portion of your budget to the full rollout. Your team will gain valuable hands-on experience that makes the final deployment much smoother.
Finalizing the right tag for your system
Your choices regarding memory capacity and data formatting directly dictate the overall success and reliability of your deployment. By understanding the distinct differences between basic identification codes and localized data storage, you can confidently specify the exact hardware requirements for your upcoming project. The RFID & NFC platform remains a neutral educational resource dedicated to helping your business make informed and highly practical integration decisions. Approaching your tag selection with this structured knowledge guarantees a robust architecture that perfectly supports your operational workflow.
How much data can typical RFID and NFC tags store?
Most passive Radio Frequency Identification (RFID) and Near Field Communication (NFC) tags store small amounts of data. Ultra High Frequency (UHF) RFID for inventory typically offers 96 to 128 bits for the Electronic Product Code (EPC) plus 0 to 512 or more bits of user memory. Common NFC chips provide 144 to 888 bytes, and secure cards reach about 8 kilobytes.
How is memory laid out on a typical UHF RFID tag?
On supply chain tags, memory follows the Electronic Product Code Generation 2 (EPC Gen2) layout with four logical sections. Reserved holds two passwords. EPC stores the item code. Tag Identifier (TID) is factory set and read only. User memory is optional and varies widely by chip.
What lives in the tag identifier bank, and can I change it?
That bank stores the chip maker, the model, and a unique silicon serial number. The Tag Identifier (TID) is written at the factory and cannot be changed. You use it to verify authenticity and to distinguish chip families during testing.
How does NDEF structure data on an NFC tag?
The NFC Data Exchange Format (NDEF) wraps data into a message made of one or more records. Each record includes a header, a type, an optional identifier, and a payload such as a web link or text. Keep payloads short to fit the tag’s limited memory.
Should I store data on the tag or in my system?
Store only a short identifier on the tag and keep full details in your backend system, meaning your server or database. Heavy payloads and logs fill tags quickly, and frequent writes wear memory over time. For offline logging, use an active logger and read it via NFC.